essay on programming languages, computer science, information techonlogies and all.

Wednesday, July 24, 2013

Properties of chain code i.e. perimeter, area and center of mass

The chain code is compact and efficient to store and transfer. Though it is not that straight forward to calculate some properties of shape .i.e area, perimeter and center of mass.

Perimeter is relatively easy and from Bernd Jähne book ( Digital Image Processing 5th: 508-511 ), it can be calculated as below code.
  double CalculatePerimeter( const ChainCode& chains )
  {
    double p = 0;
    double sqrt2 = sqrt( 2.0 );

    for( size_t i=0; i < chains.size(); ++i )
    {
      if( chains[i]%2 == 0 ) 
      {
        p += 1.0;
      }
      else
      {
        p += sqrt2;
      }
    }

    return p;
  }
Bernd Jähne also showed how to get the area using a chain code but it doesn't work well when the chain code is 1 pixel width or height e.g. ( 0 0 4 4 ) will return 2 instead of 3. Refer below image how the area end up 1 pixel short.


Cris Luengo ( Cris's Image Analysis Blog : More chain code measures ) shows a matlab code that works well with 1 pixel wide chain code. In above case of 3 pixels, it adds two more addition when the direction changes which add up 1 more pixel. Refer below image.
Here is the C/C++ code snippet that is converted from the above Cris Luengo's matlab code.

// making a circular chain code by inserting the last code to the front 
ChainCode cc;
cc.push_back( chains[ chains.size()-1 ] );
for( size_t i=0; i < chains.size(); ++i )
{
  cc.push_back( chains[i] );
}
m_Area = CalculateArea( cc );


int CalculateArea( const ChainCode& cc ) // a circular chain
{
  int (&M)[8][8]( TableAreaIncrement );
  int B = 10, A = 0;

  for( size_t i=1; i < cc.size(); ++i )
  {
    uint8_t c_i = cc[i];
    uint8_t c_im1 = cc[i-1];

    switch( M[c_im1][c_i] )
    {
    case 'X' :
      throw Exception( StringFormat::As( _T("Invalid chain code found as %d->%d"), 
        c_im1, c_i ));
    case 'A': A += -B+1;  break;
    case 'B': A += -B;    break;
    case 'C': A += B;    break;
    case 'D': A += B-1;    break;
    }

    switch( c_i )
    {
    case 0: A+=B;      break;
    case 1: A+=(++B);    break;
    case 2: B++;      break;
    case 3: A+=-(++B)+1;  break;
    case 4: A+=-B+1;    break;
    case 5: A+=-(--B)+1;  break;
    case 6: B--;      break;
    case 7: A+=(--B);    break;
    }
  }

  return A;
}
  
int ChainCodeProperties::TableAreaIncrement[8][8] = 
{
  {'0','1','B','X','A','A','6','7'},
  {'0','1','B','B','X','A','6','7'},
  {'C','C','2','3','4','X','C','C'},
  {'C','C','2','3','4','5','X','C'},
  {'C','C','2','3','4','5','D','X'},
  {'X','C','2','3','4','5','D','D'},
  {'0','X','A','A','A','A','6','7'},
  {'0','1','X','A','A','A','6','7'},
};

The center of mass can be calculated by summing up x and y coordinates. But just simply adding up does not cover 1 pixel wide chain code as below image. The (1,1) pixel added two times instead one time. The compensation can be done by adding more pixels when a direction changes in opposite way as the idea of Cris Luengo's area calculation.
Below is the C/C++ code snippet that calculate the centroid.
void CalculateCentroid( const ChainCode& cc, double* cx, double *cy )
{
  int (&O)[8][2]( TableOffsetIncrement );
  int vpc = 0;      // visitied pixel count
  int sx = 0, sy = 0;    // sum of x and y
  int px = 0, py = 0;
  
  for( size_t i=1; i < cc.size(); ++i )
  {
    uint8_t c_i = cc[i];
    uint8_t c_im1 = cc[i-1];

    if( c_i != c_im1 && (c_i & 0x3 ) == ( c_im1 & 0x3 ) )
    {
      // when direction changes in opposite direction 
      // e.g. 0 -> 4, 4 -> 0, 1 -> 5, ...
      vpc++; sx += px;  sy+=py;
    }

    px += O[ c_i ][0];
    py += O[ c_i ][1];

    vpc++; sx += px;  sy+=py;
  }

  *cx = (double)sx / (double)vpc;
  *cy = (double)sy / (double)vpc;
}

int ChainCodeProperties::TableOffsetIncrement[8][2] =
{
  { 1,  0  },
  { 1,  -1  },
  { 0,  -1  },
  { -1,   -1  },
  { -1,  0  },
  { -1,  1 },
  { 0,  1 },
  { 1,  1 },
};  
It works well most of the case but it fails if there is a pixel which is visited more than 2 times as below image. It has (1,1) pixel counted 3 times but it should be counted 2 times.


Monday, July 8, 2013

Contour tracing by Moore Neighbor Algorithm

Having a binary image with defects, it is time to find out how the defects looks like. The location and size is what we want to figure out. Though we need to extract the defect from the image first. This is called segmentation and there are two methods. One is contour detection and the other is region coloring.

Region coloring is to put a unique label to a separated component. At first it labels all the pixels in a way and at a second phase, those labels are merged when connected. The result of the region coloring is still a area image with each component assigned with a unique number. And if you want to count how many defects are there, the area has to be scanned and count unique number. Or if you want to transmit the defect information, the whole labeled image has to be sent out - though the size can be much smaller than original image if run length encoding is used.

Contour detection is to trace the defect pixels and extract contour only. This start on a pixel and keep following on nearby defect pixels until it comes back to the start pixel. The result of this segmentation is only contour pixels and can apply chain coding which takes 3 bits per pixel. And it makes quite small size and compact to transmit to other. This contour information can be used to calculate area or moment for analysis.

There are number of algorithms for contour tracing. Refer [CTA]. The square tracing doesn't work with 8 neighbor hood. The Moore-Neighbor tracing and radial sweep algorithms are almost identical. Theo Pavlidis's algorithm is not that easy to implement.

In here, I will show implementation of Moore-Neighbor Tracing based on the above web site. Though the stop condition at the web site is not so simple and will use approach from other book - P192 of [IPA] as below exerpt.
  If the current boundary element Pn is equal to the second border element P1 , and
  if the previous border element Pn-1 is equal to Po , stop. Otherwise repeat step 2.
First the image has to be traversed to find the start point. And when found a pixel, do the contour tracing and clear out the traced object so that it does not get picked up again. Here is the code snippet.
void Build( BinaryImageBase& image, const Region& roi, PointsContainer* contours ) 
{
  for( int sy = roi.Top; sy<= roi.Bottom; ++sy )
  {
    for( int sx = roi.Left; sx<=roi.Right; ++sx )
    {
      if( image.GetPixel( sx, sy ) == false )
        continue;

      Points contour;
      m_Tracer->Trace( image, roi, Point((uint16_t)sx,(uint16_t)sy), &contour ); // MooreNeighbor Tracing
      m_Filler->Fill( image, contour[0], false );  // FloodFill
    
      contours->push_back( contour );
    }
  }
}
The Moore-Neighbor tracing can be implemented as below.
struct WalkTableItem
{
  Point Step;
  int Next;
} WalkTable[8] =
{
  { Point(1,0),   6, },  // from North to North-East, when found pixel, start from index 6 of this table
  { Point(0,1),  0, },   // from North-East to East
  { Point(0,1),  0, },   // from East to South-East
  { Point(-1,0),  2, },  // from South-East to South
  { Point(-1,0),  2, },  // from South to South-West
  { Point(0,-1),  4, },  // from South-West to West
  { Point(0,-1),  4, },  // from West to North-West
  { Point(1,0),  6, },   // from North-West to North
};

void Trace( const BinaryImageBase& image, const Region& roi, const Point& start, Points* trace )
{
  const int SizeOfT = sizeof(WalkTable)/sizeof(WalkTable[0]);
  WalkTableItem (&T)[SizeOfT]( WalkTable );   // access WalkTable with variable name T for short

  Points B; B.push_back( start );             // B is the container of points
  int sk = 0, k = 0;                          // sk is the start index, k is current index
  Point c = start - T[k].Step;                // c is current point
  k = T[k].Next;
  sk = ( SizeOfT + k - 1 ) % SizeOfT;

  for( ; ; ) 
  {
    Point n = c + T[k].Step;                  // n is next point
    if( image.GetPixel( n.As.XY.X, n.As.XY.Y ) == true ) 
    {
      size_t bc = B.size();

      if( bc > 2 && n == B[1] && B[bc-1] == B[0] )  
      {
        break;                                 // end condition by [IPA]
      }
      else
      {
        B.push_back( n );                      // found contour pixel
        n = c;                                 // back-track
        k = T[k].Next;                         // next index to search 
        sk = ( SizeOfT + k - 1 ) % SizeOfT;    // stop index if no pixel at moore-neighbor
      }
    }
    else
    {
      k = (k+1) % SizeOfT;                      // move to next index 
    }

    c = n;
    if( sk == k )                               // stop condition with 1 pixel defect
    {
      break;
    }
  }

  if( B.size() == 1 )                           
  {
    trace->swap( B );                           // 1 pixel defect
  }
  else
  {
    trace->swap( Points( &B[0], &B[ B.size() - 1 ] ) );  // The last pixel is the start pixel so exclude it.
  }
}
Here is code of stack-based FloodFill based on [WFF].
void Fill( BinaryImageBase& image, const Point& start, bool fillValue )
{
  std::stack< Point > Q;
  Q.push( start );

  while( Q.size() != 0 )
  {
    Point p = Q.top();
    Q.pop();

    if( p.As.XY.X < 0 || p.As.XY.X >= image.GetWidth() ||
      p.As.XY.Y < 0 || p.As.XY.Y >= image.GetHeight() )
      continue;

    if( image.GetPixel( p.As.XY.X, p.As.XY.Y ) == fillValue ) 
      continue;

    image.SetPixel( p.As.XY.X, p.As.XY.Y, fillValue );

    Q.push( Point( p.As.XY.X + 1, p.As.XY.Y ) );
    Q.push( Point( p.As.XY.X - 1, p.As.XY.Y ) );

    Q.push( Point( p.As.XY.X + 1, p.As.XY.Y - 1 ) );
    Q.push( Point( p.As.XY.X,     p.As.XY.Y - 1 ) );
    Q.push( Point( p.As.XY.X - 1, p.As.XY.Y - 1 ) );

    Q.push( Point( p.As.XY.X + 1, p.As.XY.Y + 1 ) );
    Q.push( Point( p.As.XY.X,     p.As.XY.Y + 1 ) );
    Q.push( Point( p.As.XY.X - 1, p.As.XY.Y + 1 ) );
  }
}

The result of contour tracing is boundary pixels and one or more pixels can be repeated as it needs to return to the original image. Refer below image and it's result.
Contour pixels : (1,1),(2,2),(3,1),(2,2),(3,3),(2,2)


Reference :
[CTA] Contour Tracing WEB Site by Abeer George Ghuneim
[IPA] Image Processing, Analysis and Machine Vision by Milan Sonka, Vaclav Hlavac, Roger Boyle.
[WFF] FloodFill from Wikipedia

Wednesday, June 19, 2013

OpenCL - Connecting pixels

Sometimes, it can happens that number of 1 pixel defects scattered around closely. When the pixels are close enough it is better to consider as a 1 defects rather than separate defects.

To merge number of close pixels, we can use closing - dilation and erosion. This does add pixels between horizontal or vertical distanced pixels. But it doesn't fill the gap between diagonal distance. Refer below two images which shows original image and image after closing.


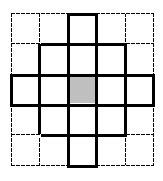
This is because the dilation is spreading to 8 neighbor pixels like below.

To fill a gap at a diagonal distanced pixels, the dilation should cover more as below.

When this 2 pixel distance dilation is used, the diagonal distance is filled as below.
This 2 pixel dilation code is as below.
__kernel
void Dilation2PixelDistance(
  __global uchar *d_src, 
  __global uchar *d_dst,
  int width, int height,
  int roiLeft, int roiTop, int roiRight, int roiBottom )
{ 
  int x = (roiLeft & (~0x07)) + ( get_global_id(0) << 3 );
  int y = roiTop + get_global_id(1);
  int stride = width >> 3;

  if( x <= roiRight ) 
  {
    int idx = x + (y-2) * width;
    int bidx = idx >> 3;

    uchar dilated = 0, C;

    if( y > roiTop+1 ) 
    {
      C = d_src[bidx];
      dilated |= C;
    }

    bidx += stride;
    if( y > roiTop ) 
    {
      C = d_src[bidx];
      dilated |= C;
      dilated |= (C >> 1) | ( d_src[bidx-1] << 7);
      dilated |= (C << 1) | ( d_src[bidx+1] >> 7);
    }

    bidx += stride;
    if( y <= roiBottom )
    {
      C = d_src[ bidx ];
      dilated |= C;
      dilated |= (C >> 2) | (d_src[ bidx - 1] << 6);
      dilated |= (C >> 1) | (d_src[ bidx - 1] << 7);
      dilated |= (C << 1) | (d_src[ bidx + 1] >> 7);
      dilated |= (C << 2) | (d_src[ bidx + 1] >> 6);
    }

    bidx += stride;
    if( y < roiBottom )
    {
      C = d_src[ bidx ];
      dilated |= d_src[ bidx ];
      dilated |= (C >> 1) | (d_src[ bidx - 1] << 7);
      dilated |= (C << 1) | (d_src[ bidx + 1] >> 7);
    }

    bidx += stride;
    if( y < roiBottom -1 )
    {
      C = d_src[bidx];
      dilated |= C;
    }

    bidx -= (stride<<1);
    if( y <= roiBottom )
    {
      d_dst[ bidx ] = dilated;
    }
  }
}   
The closing operation - 2 pixel dilation & erosion - runs at 1.84 GB/s. Refer below profiling result.
Step 1 : start 0 ns, end 103840 ns, duration 103840 ns, 38243.76 MB/s              : copying source image to device
Step 2 : start 323584 ns, end 837440 ns, duration 513856 ns, 7728.30 MB/s          : 2 pixel dilation
Step 3 : start 1730560 ns, end 2041888 ns, duration 311328 ns, 12755.78 MB/s       : erosion
Step 4 : start 2072288 ns, end 2153088 ns, duration 80800 ns, 49148.92 MB/s        : copying result image from device
Total : duration 2153088 ns, 1844.44 MB/s

Saturday, June 15, 2013

OpenCL - Dilation and Erosion in packed bit

With packed binary pixel - 1 bit per pixel - morphology operation can be done with number of bits together. i.e. 8 pixels - 1 byte - can be read and dilated and eroded in a go. When morphology is done in unit of byte, then the number of thread needs is pixel count divide by 8. Below is a OpenCL kernel code that does dilation in 8 neighbor hood.
__kernel void Dilation( 
  __global uchar *d_src, 
  __global uchar *d_dst,
  int width, int height,
  int roiLeft, int roiTop, int roiRight, int roiBottom )
{ 
  int x = (roiLeft & (~0x07)) + ( get_global_id(0) << 3 );
  int y = roiTop + get_global_id(1);
  int stride = width >> 3;

  if( x <= roiRight ) 
  {
    int idx = x + (y-1) * width;
    int bidx = idx >> 3;

    uchar dilated = 0, C;

    if( y > roiTop ) 
    {
      C = d_src[bidx];
      dilated |= C;                                   // North
      dilated |= (C >> 1) | ( d_src[bidx-1] << 7);    // North West
      dilated |= (C << 1) | ( d_src[bidx+1] >> 7);    // North East
    }

    bidx += stride;
    if( y <= roiBottom )
    {
      C = d_src[ bidx ];
      dilated |= C;                                    // Center
      dilated |= (C >> 1) | (d_src[ bidx - 1] << 7);   // West
      dilated |= (C << 1) | (d_src[ bidx + 1] >> 7);   // East
    }

    bidx += stride;
    if( y < roiBottom )
    {
      C = d_src[ bidx ];
      dilated |= d_src[ bidx ];                        // South
      dilated |= (C >> 1) | (d_src[ bidx - 1] << 7);   // South West
      dilated |= (C << 1) | (d_src[ bidx + 1] >> 7);   // South East
    }

    bidx -= stride;
    if( y <= roiBottom )
    {
      d_dst[ bidx ] = dilated;
    }
  }
}   
Below is a OpenCL kernel code that does erosion in 8 neighbor hood.
__kernel
void Erosion(
  __global uchar *d_src, 
  __global uchar *d_dst,
  int width, int height,
  int roiLeft, int roiTop, int roiRight, int roiBottom )
{ 
  int x = (roiLeft & (~0x07)) + ( get_global_id(0) << 3 );
  int y = roiTop + get_global_id(1);
  int stride = width >> 3;

  if( x <= roiRight ) 
  {
    int idx = x + (y-1) * width;
    int bidx = idx >> 3;

    uchar eroded = 0xFF, C;

    if( y > roiTop ) 
    {
      C = d_src[bidx];
      eroded &= C;
      eroded &= (C >> 1) | ( d_src[bidx-1] << 7);
      eroded &= (C << 1) | ( d_src[bidx+1] >> 7);
    }

    bidx += stride;
    if( y <= roiBottom )
    {
      C = d_src[ bidx ];
      eroded &= C;
      eroded &= (C >> 1) | (d_src[ bidx - 1] << 7);
      eroded &= (C << 1) | (d_src[ bidx + 1] >> 7);
    }

    bidx += stride;
    if( y < roiBottom )
    {
      C = d_src[ bidx ];
      eroded &= d_src[ bidx ];
      eroded &= (C >> 1) | (d_src[ bidx - 1] << 7);
      eroded &= (C << 1) | (d_src[ bidx + 1] >> 7);
    }

    bidx -= stride;
    if( y <= roiBottom )
    {
      d_dst[ bidx ] = eroded;
    }
  }
}   

Thursday, May 9, 2013

LibPng with png++

To debug the inspection algorithm, the straight forward way is to look at the image. Though display image, there are lot of things to consider. Window, panning, zooming, display coordinates, display pixel value, bits per pixel, pixel aliasing, speed, ... . One simple way is to save the image to a file and then open with a off-the-shelf image viewer.

There are lots of image viewer and one is MeeSoft Image Analyzer. It supports lots of image format and displayed pixels are not anti-aliased.

There are also lots of image format. Though in here, I want wide-spread, loseless, support binary packed pixel and royalty-free image format. I choose PNG file format.

To manipulate PNG file format, there is LibPng for Windows. Also there is C++ wrapper project png++. To use LibPng, zlib is also needed for compression/decompression.

To setup, you need to download binaries and developer files from above link and extract it to some place. I extracted at 3rdParty folder.

Then modify the project's 'Additional Include Directories' with below directories. Prefixed "../" depends on the relative depth between project to the 3rdParty folder.
  "../../../3rdParty/libpng-1.2.37/include";
  "../../../3rdParty/zlib-1.2.3/include";
  "../../../3rdParty/png++-0.2.5";

Then modify Library Directories with below path.
"../../../3rdParty/libpng-1.2.37/lib"

Then add '__Win32' to the Processor Definition. This is for png++ and without it, you will see below error.
  /3rdparty/png++-0.2.5/config.hpp(57) : fatal error C1189: #error :  Byte-order could not be detected.

There is one more step that needs attention on zlib. The zlib is trying to include unistd.h in Windows and there seems no other way but to comments the line out. Maybe I missed a step in the setup. Anyway with this line removed, it make the project compile and link though I don't know the implication. Refer below for the change.
zconf.h at line 289

#if 1           /* HAVE_UNISTD_H -- this line is updated by ./configure */
#  include  /* for off_t */
//#  include     /* for SEEK_* and off_t */ // commented out 
...
#endif

When the project is executed, it will look for the dlls for libpng and zlib. This can go to the system32 folder but in here I copied those file to the output folder using 'Post build event' as below.
  xcopy "../../../3rdParty/libpng-1.2.37/bin/libpng12.dll" "$(TargetDir)" /Y
  xcopy "../../../3rdParty/zlib-1.2.3/bin/zlib1.dll" "$(TargetDir)" /Y
Now all set and code like below will save any image to png file.
#pragma warning( push, 3 )
#pragma warning( disable : 4996 4267 4355 )  // there are number warnings that may not be a problem at all ...
#include < png.hpp >
#pragma warning( pop )
#include "Image.hpp"     // Image<> and BinaryImage<> are defined in here
#include < iostream >

#pragma comment(lib, "libpng.lib" ) 

// Most of this template class comes from png++ example. 
template < typename TImage, typename PngPixelType >
class ImagePngWriter
    : public png::generator < PngPixelType, ImagePngWriter < TImage,PngPixelType > >
{
public:
    ImagePngWriter( TImage& image )
        : png::generator < PngPixelType, ImagePngWriter > ( image.GetWidth(), image.GetHeight() ), 
          m_Image( image )
    {}

    png::byte* get_next_row(size_t pos)
    {
        return reinterpret_cast < png::byte* > ( m_Image.GetPixelPtr( 0, (int)pos ) );
    }

    void Write( const char *filename )
    {
        std::ofstream file( filename, std::ios::binary);
        write(file);
    }

private:
    TImage& m_Image;
};

usgae
  Image< boost::uint8_t > image( 640, 480 );
  ...
  ImagePngWriter< Image< boost::uint8_t >, png::gray_pixel > pngWriter( image );
  pngWriter.Write( "Gray.png" );


  BinaryImage<> image( 640, 480 );
  ...
  ImagePngWriter< BinaryImage<>, png::gray_pixel_1 > pngWriter( image );
  pngWriter.Write( "Binary.png" );

Tuesday, April 16, 2013

OpenCL - GPU, Threshold and binary image

After pitch comparison, the intensity is compared with certain threshold and if the pixel difference is above certain value, the pixel is treated as a defect. And what matter is whether the pixel is foreground or background, the result is binary value. And as binary value can be represented by 1 bit, and as it is expensive to read/write pixel through memory, the pixel is packed not to waste space.

To pack 8 binary pixels to a byte, it is needed to read result from the neighbor's binary pixel value. This neighbor's pixel can be written to a global memory and read back but that will be expensive write and read operations. Instead, we can write binary result to a local memory and read 8 pixels back and pack to a byte and write to the global memory.

Another thing to be careful is the bit order - which bit to turn on for the pixel index 0. Is it the most significant bit or least significant bit ? In here, I use the most significant bit for the pixel index 0 and decrease the bit location for increased pixel index. In this way, it is easy to read byte value and guess the location of the pixel.

Below is the kernel code

float PitchedSubPixel( __global uchar* src, int idx, float weightLeft, float weightRight )
{
  return (float)src[ idx ] * weightLeft + (float)src[ idx+1 ] * weightRight;
}

float PixelDifference( float center, float east, float west )
{
  float diff = ( center * 2.0f  - ( east + west ) ) / 2.0f;
  return diff >= 0 ? diff : -diff;
}

__kernel
void PitchThreshold(
  __global uchar *d_src, 
  __global uchar *d_dst,
  int width, int height,
  int roiLeft, int roiTop, int roiRight, int roiBottom,
  int integerPitch, float toCeiling, float toFloor,
  __local uchar *localDst,                                         // this is the local memory where temporary binary pixel is stored
  uchar threshold )
{ 
  int x = (roiLeft & (~0x07)) + get_global_id(0);                  // x always starts with multiple of 8 - byte aligned
  int y = roiTop + get_global_id(1);
  int idx = x + y * width;

  bool isInBound = x >= roiLeft && x <= roiRight && y <= roiBottom;

  float east = 0.0f, west = 0.0f, diff = 0.0f;
  if( isInBound ) 
  {
    east = PitchedSubPixel( d_src, idx-integerPitch-1, toCeiling, toFloor );
    west = PitchedSubPixel( d_src, idx+integerPitch, toFloor, toCeiling );
    diff = PixelDifference( (float)d_src[idx], east, west );
  }

  uchar binary = ((uchar)( diff ) <  threshold) ? 0 : 1;           // fixed threshold, if outside of ROI, then 0

  int localX = get_local_id(0);                                    // localX is 0 to 63. Refer host code
  int localIdx = get_local_id(1) * get_local_size(0) + localX;     // get_local_id(1) is 0 to 3. get_local_size(0) is 64 as width. Refer host code
  binary = binary << (7-(localX & 0x07));                          // i.e, if localX is 10, then it is 1 << 5,
  localDst[localIdx] = binary;                                     // putting the shifted binary value to local memory

  isInBound = x <= roiRight && y <= roiBottom;                     // ROI start at byte aligned
  
  barrier( CLK_LOCAL_MEM_FENCE );                                  // wait for the neighbor's local memory is written

  if( isInBound && (localX & 0x07) == 0 )
  {
    uchar packed =                                                 // read 8 pixels and pack as a byte 
      localDst[ localIdx   ] | localDst[ localIdx+1 ] | localDst[ localIdx+2 ] | localDst[ localIdx+3 ] | 
      localDst[ localIdx+4 ] | localDst[ localIdx+5 ] | localDst[ localIdx+6 ] | localDst[ localIdx+7 ] ; 

    d_dst[ idx >> 3 ] = packed;                                    // write to global memory
  }   
}
Below is the host code snippet
  const int LOCAL_WIDTH = 64, LOCAL_HEIGHT = 4;
  cl::NDRange localws( LOCAL_WIDTH, LOCAL_HEIGHT );
  cl::NDRange globalws( 
    LOCAL_WIDTH * (int)ceil( (double)(roiRight-roiLeft+1) / (double)LOCAL_WIDTH ), 
    LOCAL_HEIGHT * (int)ceil( (double)(roiBottom-roiTop+1) / (double)LOCAL_HEIGHT )
  );

  ...
  kernelPitch0.setArg( 11, LOCAL_WIDTH*LOCAL_HEIGHT*sizeof(uint8_t), NULL );  // request to allocate local memory
  kernelPitch0.setArg( 12, threshold );

  vector ve1; ve1.push_back( steps[1] );
  queue.enqueueNDRangeKernel( kernelPitch0, cl::NullRange, globalws, localws, &ve1, &steps[2] );

Just pitch comparison was 1.4GB/s but now it is around 1.3GB/s. Refer below time profiling.

Step 1 : start 0 ns, end 646304 ns, duration 646304 ns, 6144.53 MB/s
Step 2 : start 1086688 ns, end 2980640 ns, duration 1893952 ns, 2096.80 MB/s    <- was 3085 MB/s
Step 3 : start 3009344 ns, end 3090080 ns, duration 80736 ns, 49187.88 MB/s     <- was 6330 MB/s
Total : duration 3090080 ns, 1285.16 MB/s                                       <- was 1406 MB/s


Wednesday, April 3, 2013

OpenCL - one work group per CPU core

At the last post, I got around 1GB/s throughput but that is just utilizing only one core out of dual core CPU.

Digging up the correct multi-core usage with a kernel in Intel OpenCL SDK, found that the work group size should be same as number of cores. Then it will make each work group sits on a single core. For this OpenCL 1.1 spec says that
Compute Unit: An OpenCL device has one or more compute units. A work-group executes on a single compute unit. A compute unit is composed of one or more processing elements and local memory. A compute unit may also include dedicated texture filter units that can be accessed by its processing elements.
When making host code for GPU, I did carefully assign the work group size and local work item size. But with CPU case, I didn't pay much attention to it as there is just 2 cores. Also due to Intel recommendation at "Writing Optimal OpenCL* Code with the Intel® OpenCL SDK" as below.
2.7 Work-Group Size Considerations
We always recommend letting the OpenCL implementation to automatically determine the optimal work-group size (sometimes referred as “local work size”) for a given kernel. Simply pass NULL for a pointer to the local work size when calling clEnqueueNDRangeKernel.
But it turns out that this work group size and local work item size should be set according to number of cores. The required change is as below.
  // host code

  cl::NDRange globalws( 2 );  // 2 work items in total
  cl::NDRange localws( 1 );   // 1 work item per work group - makes up 2 work groups
  ...
  queue.enqueueNDRangeKernel( kernelPitch0, cl::NullRange, globalws, localws, NULL, &ev );
  ...

  // kernel code
  __kernel 
  __attribute__((reqd_work_group_size(1,1,1)))   // this can be specified but makes no difference for me.
  void Pitch( 
    __global const uchar *src, __global uchar *dst, 
    ...
This change makes around 2.1GB/s throughput as below.
...
Total : duration 1961850 ns, 2022.74 MB/s
Total : duration 1787610 ns, 2219.90 MB/s
Total : duration 1796190 ns, 2209.29 MB/s
...